Ingest pipelines
Ingest pipelines preprocess and transform incoming data on Elasticsearch before they get indexed. You can use pipelines to format data, remove fields, extract values from text, and enrich your data.
How it works
An ingest pipeline consists of a sequence of configurable tasks called processors. Each processor runs in succession, making a specific change to your incoming data. Once all the processors have run, the transformed data will be added to its index.
Example:
In the example below, the dissect processor is first used to extract meaningful information from one field into separate fields. Next, the lowercase processor is used to transform the text into lowercase.
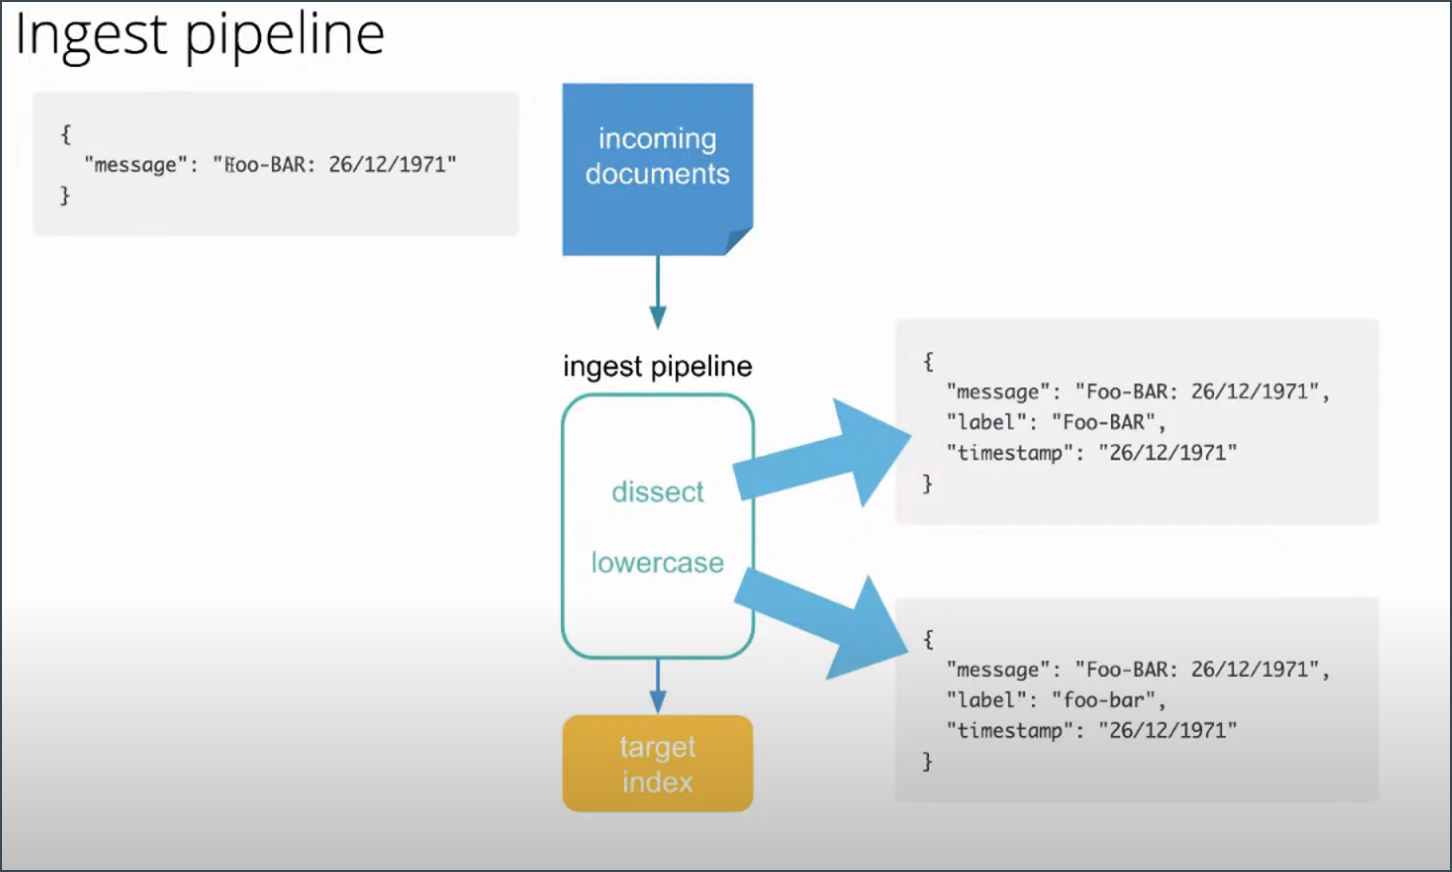 Source:Official Elastic Community
Pipeline types
There are two types of pipelines:
Managed ingest pipelines—Predefined pipelines that are created when the integration is created.
Custom ingest pipeline—Pipelines that you can create manually to define how you want to ingest and process data before indexing it into Elasticsearch. You can append them to managed pipelines.
Learn more about Custom ingest pipelines.
